We paired perception and reasoning models on NXP’s i.MX 95 to build a blueprint for agentic AI on embedded devices.
We’ve built a blueprint for agentic AI on the Toradex Verdin iMX95. In our home appliance demo, LFM2.5-VL 450M handles perception and Qwen3-0.6B handles reasoning, with both running across the CPU and NXP’s eIQ Neutron NPU, which we enabled for LLM inference jointly with NXP.
Across six benchmarked 8-bit LLMs, offloading to the NPU makes prefill up to 1.6× faster than running on all 6 CPU cores alone. Or you can keep the speed and free half the CPU: 3 cores plus the NPU match all 6 cores running CPU-only. Both models are swappable, drawn from a validated zoo of 10+ LLMs and VLMs. Torizon adds the long-term maintenance layer to keep the platform secure and updated throughout the product lifecycle.
For device makers, that means an agent that sees and reasons on the device itself, with no cloud round trip, on a platform they can keep secure for years. Today, the stack runs on a custom Yocto-based image; packaging for the Torizon OS container workflow is being finalized.
Read Juan Pisula’s post on running LLMs and VLMs on the Verdin iMX95 (Toradex blog).

Roofline will be at electronica 2026 in Munich, 10–13 November, showcasing an agricultural AI demo developed with F&S Elektronik Systeme. We’ll be featuring the demonstration on NXP’s partner display.
The collaboration brings together F&S's embedded hardware and Roofline's AI deployment infrastructure to demonstrate agricultural image analysis on NXP's i.MX 95 Applications Processor, achieving up to 6.8× faster inference using heterogeneous CPU and NPU execution compared with CPU-only execution.
Using a pretrained YOLOv7 model and aerial imagery from the PhenoBench dataset, the demo identifies crops and weeds in agricultural fields.
Roofline deployed YOLOv7 on NXP's i.MX 95 SoC, enabling execution on the CPU or across both the CPU and NPU. The 6.8× speedup demonstrates the performance benefits of using the SoC's dedicated AI accelerator rather than relying on CPU execution alone.
The demo also highlights how Roofline's MLIR- and IREE-based compiler and runtime infrastructure makes it easier to switch between AI models and execution targets, reducing integration effort and accelerating application development.
Visitors to electronica 2026 can see the joint Roofline and F&S Elektronik Systeme demonstration on NXP's partner wall.
Event: 10–13 November 2026
Location: Trade Fair Center Messe München, Munich, Germany
Visit NXP's partner display to see YOLOv7 running on the i.MX 95 SoC and compare CPU-only inference with heterogeneous CPU and NPU execution.
Find event details and visitor information for electronica 2026.
Three Roofline software engineers will present at the 2026 US LLVM Developers’ Meeting, taking place 26–28 October in Santa Clara, California:
The annual LLVM Developers’ Meeting brings together engineers and contributors working on LLVM, MLIR, Clang, and related open-source technologies to exchange technical knowledge, discuss engineering challenges, and share developments across the compiler ecosystem.
27 October 2026 | 11:30–12:00 PDT / 19:30–20:00 CET
Pooja shows how data tiling can improve convolution performance in MLIR/IREE, and where structured code generation reaches its limits. Her approach compiles 2D convolution operations directly in data-tiled form, avoiding im2col, an intermediate data transformation commonly used to implement convolutions through matrix multiplication.
The performance findings differ across CPU architectures:
Pooja investigates the performance gap using hardware performance counters, generated assembly, and code-generation experiments. Her presentation explores why efficient data layouts alone may not guarantee optimal performance and what additional microarchitecture-specific optimizations may be needed to close the gap.
28 October 2026 | 11:00–11:30 PDT / 19:00–19:30 CET
Luis shares lessons from Roofline's ongoing work on Qualcomm targets to bring up the Hexagon DSP/NPU within IREE.
His presentation follows the development process of adapting an MLIR-based end-to-end compiler to a new accelerator, starting from a CPU-based reference path and progressively introducing hardware-aware lowering.
Drawing on the Hexagon bring-up, Luis explores the systems design questions that arise when adapting existing compiler infrastructure to specialized hardware. Examples involving memory management, vectorization, and interactions between the compiler and runtime help illustrate some of the engineering decisions encountered during development.
The presentation shares practical experience from the Hexagon integration with other engineers working on MLIR-based compilers and hardware enablement.
Roofline's ongoing work is available in the IREE Hexagon plugins repository on GitHub.
28 October 2026 | 14:15–14:45 PDT / 22:15–22:45 CET
Talk: Bringing RISC-V Matrix and Vector Vendor Extensions into MLIR-based ML Compilers
Ege presents a practical approach to integrating vendor-specific RISC-V matrix and vector extensions into MLIR-based machine learning compilers. RISC-V vendors can introduce specialized instructions to accelerate machine learning workloads, but making those instructions available to compilers requires careful integration across MLIR and LLVM.
Using IREE as an open-source case study, Ege examines three approaches:
Drawing on ongoing RISC-V vendor-extension integration work in IREE, with examples from targets such as SpaceMiT and MIPS by GlobalFoundries, Ege compares the tradeoffs between development speed, maintainability, compiler optimization, and the ability to contribute changes upstream.
The three presentations offer different perspectives on compiler development, from investigating performance limitations to working through the challenges of supporting new hardware.
By presenting their work, Pooja, Luis, and Ege contribute technical findings and practical engineering experience to ongoing discussions within the LLVM and MLIR communities.
The LLVM Developers’ Meeting takes place 26–28 October 2026 at the Santa Clara Marriott in Santa Clara, California.
If you're working on MLIR, IREE, or compiler support for new hardware architectures, join Pooja, Luis, and Ege in Santa Clara to hear about their latest engineering work, discuss technical challenges, and exchange ideas with the Roofline team.
View the full 2026 LLVM Developers’ Meeting program.
Roofline will be attending PyTorch Conference North America 2026 in San Jose, with a presentation on IREE at the LF AI & Data Summit and a presence at the LF AI & Data booth.
On 19 October, Roofline's head of ecosystem and marketing, Rod Burns, will deliver a talk titled Presenting IREE on behalf of the open-source IREE project at the LF AI & Data Summit, a co-located event at the San Jose Convention Center.
IREE is an open-source compiler and runtime that simplifies AI deployment across different frameworks and hardware platforms. Built on MLIR and LLVM, IREE provides shared infrastructure for compiling and running AI models across CPUs, GPUs, and accelerators.
In the 15-minute presentation, Rod will cover:
Roofline will also be represented at the LF AI & Data booth on 20 and 21 October, where Rod will be available for two hours each day to discuss IREE, its development, and opportunities to participate in the open-source community.
View the LF AI & Data Summit event details and registration information.
On 20 August 2026, Roofline CTO Maximilian Bartel became Chair of IREE’s Technical Steering Committee (TSC), building on Roofline’s ongoing contributions to the open-source compiler and runtime project.
In this role, Maximilian helps coordinate the TSC’s work and presides over its meetings. Technical oversight remains with the TSC collectively. Roofline will continue to support IREE through engineering contributions, community participation, and efforts to grow the ecosystem.
IREE remains an open-source project within the LF AI & Data Foundation, which supports open-source AI and data projects under the Linux Foundation.
Since 2019, the IREE project has developed an MLIR-based compiler and runtime for machine learning deployment. Its architecture supports targets ranging from data center systems to mobile and edge devices through a common compiler and runtime foundation.
IREE joined the LF AI & Data Foundation as a sandbox-stage project in May 2024. As of October 2026, LFX Insights records 1,313 contributors across the project, while the main IREE repository has almost 4,000 GitHub stars and over 1,000 forks.
Our work with IREE builds on an established commitment to the project. We use MLIR and IREE as the foundation for the edge AI deployment infrastructure we’re building, to make it easier to deploy AI across different hardware while reducing repeated integration work as models and hardware evolve.
Our engineers contribute to IREE, with more than 1,000 Roofline contributions recorded by LFX Insights over the past year. We also use IREE in real hardware deployments, organize and participate in community meetings, and contribute major technical capabilities to the project, including compiler support for Mixture-of-Experts (MoE) models.
We’ll continue contributing engineering work to IREE and helping to grow the IREE ecosystem. We want to encourage broader participation from semiconductor and IP companies, research organizations, and technical contributors working on AI deployment infrastructure.
IREE is the most scalable deployment infrastructure for edge AI across rapidly changing models and increasingly diverse target hardware. It can import models from frameworks including JAX, ONNX, PyTorch, and TensorFlow, then compile them for a range of supported operating systems, processor architectures, and accelerators through a common compiler and runtime foundation.
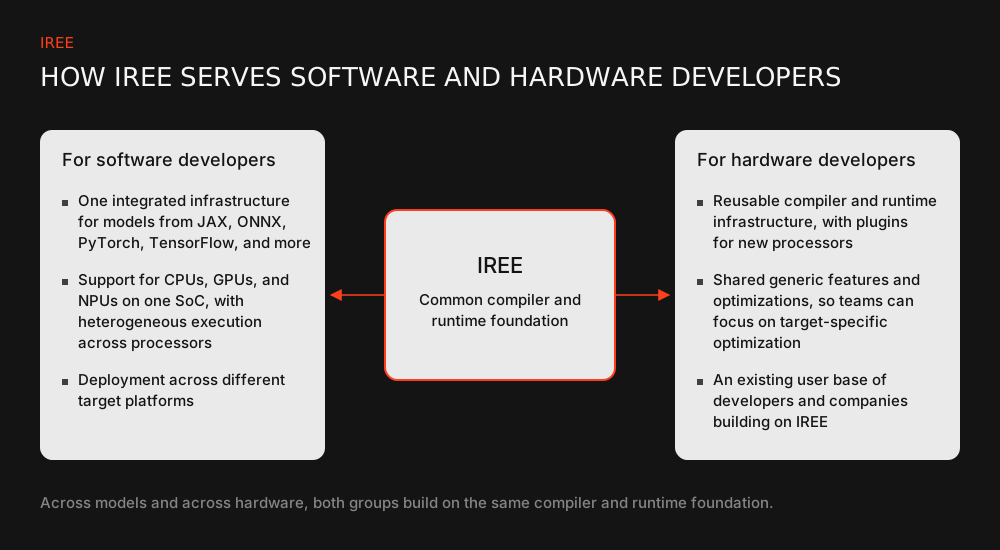
For software developers, IREE reduces the need to use a different vendor-specific deployment toolchain for every hardware target. Hardware backends provide target-specific code generation and optimization, so application teams can focus on the product rather than manually adapting models for each processor.
For hardware developers, IREE provides a shared compiler and runtime foundation that can be extended to support new processors. Compiler plugins can add new targets and dialects, while hardware abstraction layer drivers connect compiled programs to devices at runtime. New hardware still requires target-specific enablement, but the surrounding model-import, compiler, and runtime infrastructure can be reused rather than rebuilt from scratch.
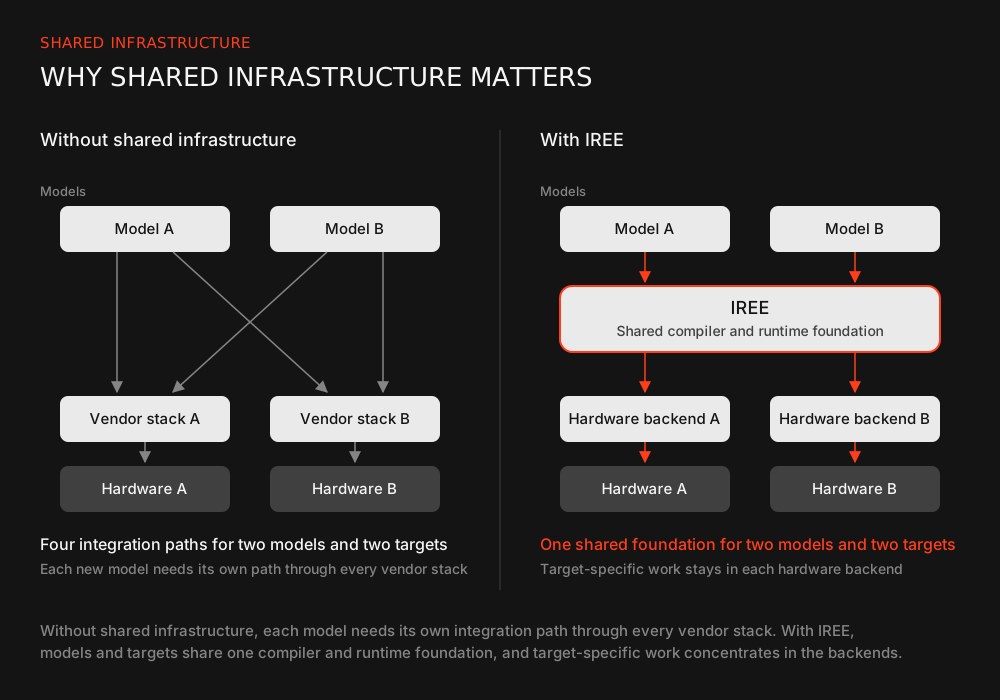
We want to strengthen IREE as shared infrastructure for deploying AI across CPUs, GPUs, NPUs, and heterogeneous systems.
“We’re increasing our engineering investment in IREE, not only by contributing code, but by taking on more responsibility for reviewing pull requests and maintaining areas of the project. A healthy open-source project needs engineers to help carry the ongoing maintenance work as well as contribute new features. We’re committing more Roofline engineering time to that ongoing effort, and we hope more contributors will join us in carrying it forward.”
— Maximilian Bartel, CTO at Roofline and Chair of the IREE Technical Steering Committee
Broader participation is an important part of strengthening IREE. We want more semiconductor and IP companies, research organizations, engineers, and researchers involved in the project, bringing new hardware requirements and technical expertise into the community.
A wider contributor and maintainer base helps IREE reflect more real hardware requirements, spreads the work of solving common deployment problems across the ecosystem, and keeps the project useful across different processors, products, and commercial interests as AI deployment requirements evolve.
Roofline contributes to IREE alongside other organizations and individual developers. Maximilian’s role as TSC Chair operates within the project’s existing governance structure, with technical decisions made through the TSC’s established processes.
IREE remains an open-source, sandbox-stage project within the LF AI & Data Foundation. The IREE Technical Steering Committee oversees the project’s technical direction under the IREE Technical Charter, and TSC meetings are open to everyone.
Our CTO, Maximilian Bartel, is serving as Chair of the TSC. The Chair presides over TSC meetings and helps coordinate the committee’s work, but technical oversight remains with the TSC rather than with Roofline or the Chair individually. The TSC elects its Chair from within the project’s governance structure.
Developers can participate through IREE’s GitHub repositories, issues, technical discussions, and community channels. Engineers and organizations can contribute code or documentation, join technical discussions, and help maintain areas of the project.
Our open-source work and our commercial deployment work use the same underlying compiler and runtime foundations.
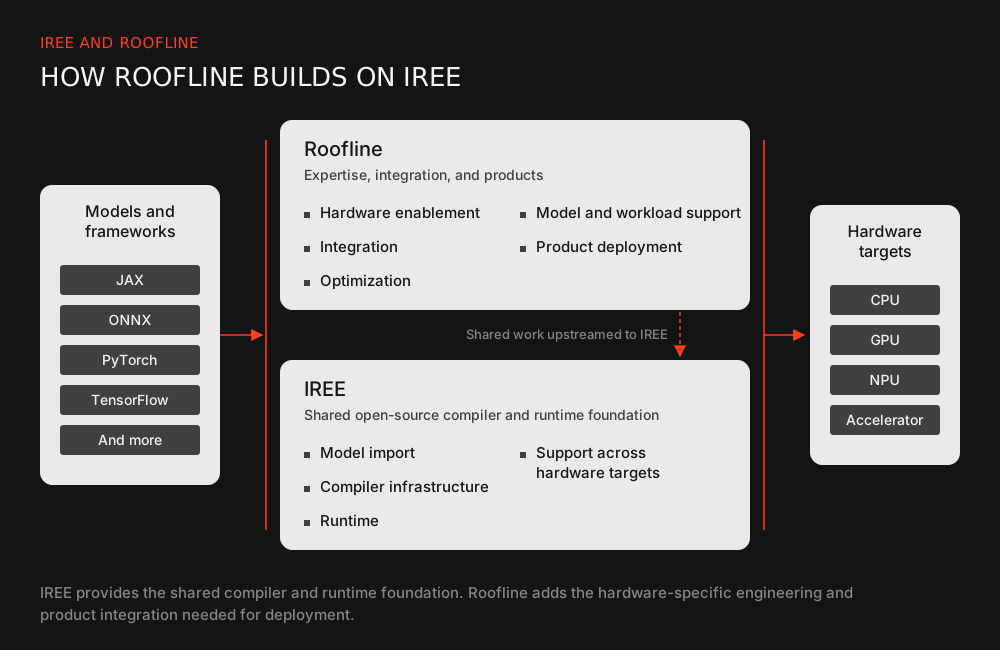
When we solve a deployment problem that belongs in shared infrastructure, the underlying capability can strengthen the common foundation rather than remaining isolated within one hardware integration. When other IREE contributors improve shared compiler and runtime infrastructure, we can build on those improvements too.
The practical benefit is less repeated generic engineering as models and hardware evolve.
IREE provides the shared compiler and runtime foundation for deploying AI across different hardware targets. Roofline turns that foundation into product-ready deployment infrastructure through hardware enablement, integration, and the validation and testing of the models and targets our customers need.
IREE already has an active contributor community, open technical governance, and a growing role in AI deployment infrastructure.
We want more engineers and organizations working on compilers, runtimes, AI hardware, and model deployment to participate in the project, so IREE can reflect a wider range of real deployment requirements and remain useful across different hardware and use cases.
There are several ways to get involved. You can contribute code or documentation through the IREE GitHub repository, open or respond to issues, join technical discussions, attend community and TSC meetings, or help maintain an area of the project. Organizations can also bring new hardware requirements, deployment challenges, and engineering experience into the community.
IREE will be stronger if the people building AI hardware and deployment software help shape the shared infrastructure they depend on. We want to make it easier for more engineers and organizations to contribute, collaborate, and help IREE evolve with the models, hardware, and deployment requirements still to come.
If you have questions, ideas, or want to get involved, join the conversation through IREE GitHub Discussions or the IREE Discord. You can also take part in community meetings to discuss technical work, project priorities, and areas where contributors can help.
Today, Liquid AI released their new 230M parameter LLM. In their words, it's "the smallest model yet, built to run anywhere (CPUs, NPUs, and GPUs) to enable agentic applications on phones, robots, home and network automation devices.
"We are excited to showcase day-0 support with roofline's deployment tools.
Agentic home automation sounded exciting, so the demo below features a smart washing machine running a full multimodal workflow: LFM2.5-VL-450M provides visual intelligence, while LFM2.5-230M serves as the orchestration agent controlling the machine.
Both models are fully compiled and run on the CPU and eIQ® Neutron NPU on NXP Semiconductors' i.MX 95, demonstrating how new foundation models can instantly move from release to real-world edge deployments.Congrats to the Liquid AI team on the release!
#EdgeAI#AIDeployment#AICompiler#MLIR#IREE#Roofline#CoFundedByTheEU
MoE powers many of today's strongest LLMs. By activating only the experts each token actually needs, it packs far more performance into the same compute budget, a limited resource on the edge. But this only pays off if your deployment stack can handle the dynamic expert routing MoE depends on, and until now, edge AI compilers couldn't.
roofline closes this gap by bringing native MoE support to its IREE-based deployment stack.
In our latest case study, we compile and run MoE models end-to-end, from IBM's Granite 3.1 1B-A400M, through Liquid AI's LFM2-8B-A1B, up to Qwen-REAP-15B-A3B. The case study walks through the operators that were missing, how we enabled them, and includes a demo of the compiled models running end-to-end: https://lnkd.in/eqqtneKV
#EdgeAI#AIDeployment#AICompiler#MLIR#MoE#Roofline#CoFundedByTheEU