

Three Roofline software engineers will present at the 2026 US LLVM Developers’ Meeting, taking place 26–28 October in Santa Clara, California:
The annual LLVM Developers’ Meeting brings together engineers and contributors working on LLVM, MLIR, Clang, and related open-source technologies to exchange technical knowledge, discuss engineering challenges, and share developments across the compiler ecosystem.
27 October 2026 | 11:30–12:00 PDT / 19:30–20:00 CET
Pooja shows how data tiling can improve convolution performance in MLIR/IREE, and where structured code generation reaches its limits. Her approach compiles 2D convolution operations directly in data-tiled form, avoiding im2col, an intermediate data transformation commonly used to implement convolutions through matrix multiplication.
The performance findings differ across CPU architectures:
Pooja investigates the performance gap using hardware performance counters, generated assembly, and code-generation experiments. Her presentation explores why efficient data layouts alone may not guarantee optimal performance and what additional microarchitecture-specific optimizations may be needed to close the gap.
28 October 2026 | 11:00–11:30 PDT / 19:00–19:30 CET
Luis shares lessons from Roofline's ongoing work on Qualcomm targets to bring up the Hexagon DSP/NPU within IREE.
His presentation follows the development process of adapting an MLIR-based end-to-end compiler to a new accelerator, starting from a CPU-based reference path and progressively introducing hardware-aware lowering.
Drawing on the Hexagon bring-up, Luis explores the systems design questions that arise when adapting existing compiler infrastructure to specialized hardware. Examples involving memory management, vectorization, and interactions between the compiler and runtime help illustrate some of the engineering decisions encountered during development.
The presentation shares practical experience from the Hexagon integration with other engineers working on MLIR-based compilers and hardware enablement.
Roofline's ongoing work is available in the IREE Hexagon plugins repository on GitHub.
28 October 2026 | 14:15–14:45 PDT / 22:15–22:45 CET
Talk: Bringing RISC-V Matrix and Vector Vendor Extensions into MLIR-based ML Compilers
Ege presents a practical approach to integrating vendor-specific RISC-V matrix and vector extensions into MLIR-based machine learning compilers. RISC-V vendors can introduce specialized instructions to accelerate machine learning workloads, but making those instructions available to compilers requires careful integration across MLIR and LLVM.
Using IREE as an open-source case study, Ege examines three approaches:
Drawing on ongoing RISC-V vendor-extension integration work in IREE, with examples from targets such as SpaceMiT and MIPS by GlobalFoundries, Ege compares the tradeoffs between development speed, maintainability, compiler optimization, and the ability to contribute changes upstream.
The three presentations offer different perspectives on compiler development, from investigating performance limitations to working through the challenges of supporting new hardware.
By presenting their work, Pooja, Luis, and Ege contribute technical findings and practical engineering experience to ongoing discussions within the LLVM and MLIR communities.
The LLVM Developers’ Meeting takes place 26–28 October 2026 at the Santa Clara Marriott in Santa Clara, California.
If you're working on MLIR, IREE, or compiler support for new hardware architectures, join Pooja, Luis, and Ege in Santa Clara to hear about their latest engineering work, discuss technical challenges, and exchange ideas with the Roofline team.
View the full 2026 LLVM Developers’ Meeting program.

Roofline will be attending PyTorch Conference North America 2026 in San Jose, with a presentation on IREE at the LF AI & Data Summit and a presence at the LF AI & Data booth.
On 19 October, Roofline's head of ecosystem and marketing, Rod Burns, will deliver a talk titled Presenting IREE on behalf of the open-source IREE project at the LF AI & Data Summit, a co-located event at the San Jose Convention Center.
IREE is an open-source compiler and runtime that simplifies AI deployment across different frameworks and hardware platforms. Built on MLIR and LLVM, IREE provides shared infrastructure for compiling and running AI models across CPUs, GPUs, and accelerators.
In the 15-minute presentation, Rod will cover:
Roofline will also be represented at the LF AI & Data booth on 20 and 21 October, where Rod will be available for two hours each day to discuss IREE, its development, and opportunities to participate in the open-source community.
View the LF AI & Data Summit event details and registration information.
On 20 August 2026, Roofline CTO Maximilian Bartel became Chair of IREE’s Technical Steering Committee (TSC), building on Roofline’s ongoing contributions to the open-source compiler and runtime project.
In this role, Maximilian helps coordinate the TSC’s work and presides over its meetings. Technical oversight remains with the TSC collectively. Roofline will continue to support IREE through engineering contributions, community participation, and efforts to grow the ecosystem.
IREE remains an open-source project within the LF AI & Data Foundation, which supports open-source AI and data projects under the Linux Foundation.
Since 2019, the IREE project has developed an MLIR-based compiler and runtime for machine learning deployment. Its architecture supports targets ranging from data center systems to mobile and edge devices through a common compiler and runtime foundation.
IREE joined the LF AI & Data Foundation as a sandbox-stage project in May 2024. As of October 2026, LFX Insights records 1,313 contributors across the project, while the main IREE repository has almost 4,000 GitHub stars and over 1,000 forks.
Our work with IREE builds on an established commitment to the project. We use MLIR and IREE as the foundation for the edge AI deployment infrastructure we’re building, to make it easier to deploy AI across different hardware while reducing repeated integration work as models and hardware evolve.
Our engineers contribute to IREE, with more than 1,000 Roofline contributions recorded by LFX Insights over the past year. We also use IREE in real hardware deployments, organize and participate in community meetings, and contribute major technical capabilities to the project, including compiler support for Mixture-of-Experts (MoE) models.
We’ll continue contributing engineering work to IREE and helping to grow the IREE ecosystem. We want to encourage broader participation from semiconductor and IP companies, research organizations, and technical contributors working on AI deployment infrastructure.
IREE is the most scalable deployment infrastructure for edge AI across rapidly changing models and increasingly diverse target hardware. It can import models from frameworks including JAX, ONNX, PyTorch, and TensorFlow, then compile them for a range of supported operating systems, processor architectures, and accelerators through a common compiler and runtime foundation.
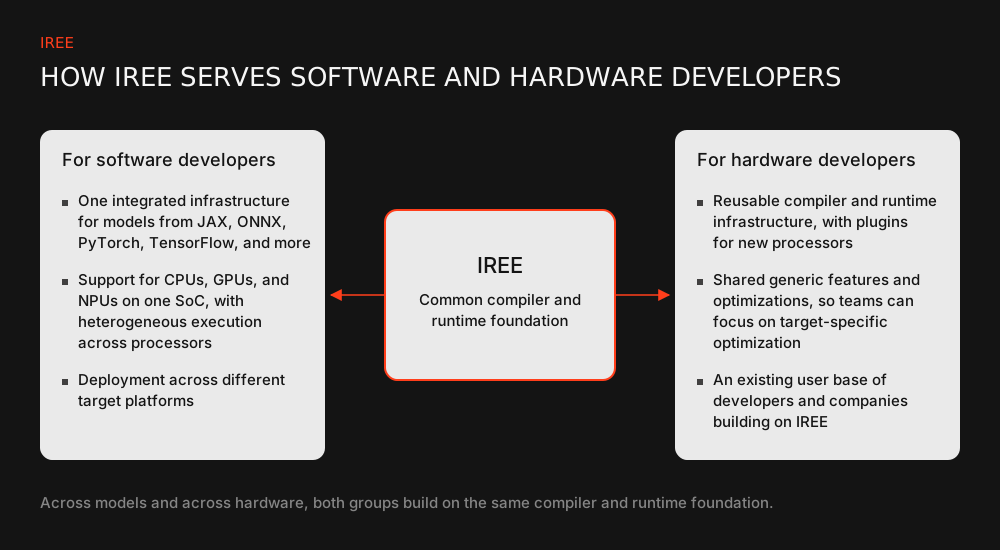
For software developers, IREE reduces the need to use a different vendor-specific deployment toolchain for every hardware target. Hardware backends provide target-specific code generation and optimization, so application teams can focus on the product rather than manually adapting models for each processor.
For hardware developers, IREE provides a shared compiler and runtime foundation that can be extended to support new processors. Compiler plugins can add new targets and dialects, while hardware abstraction layer drivers connect compiled programs to devices at runtime. New hardware still requires target-specific enablement, but the surrounding model-import, compiler, and runtime infrastructure can be reused rather than rebuilt from scratch.
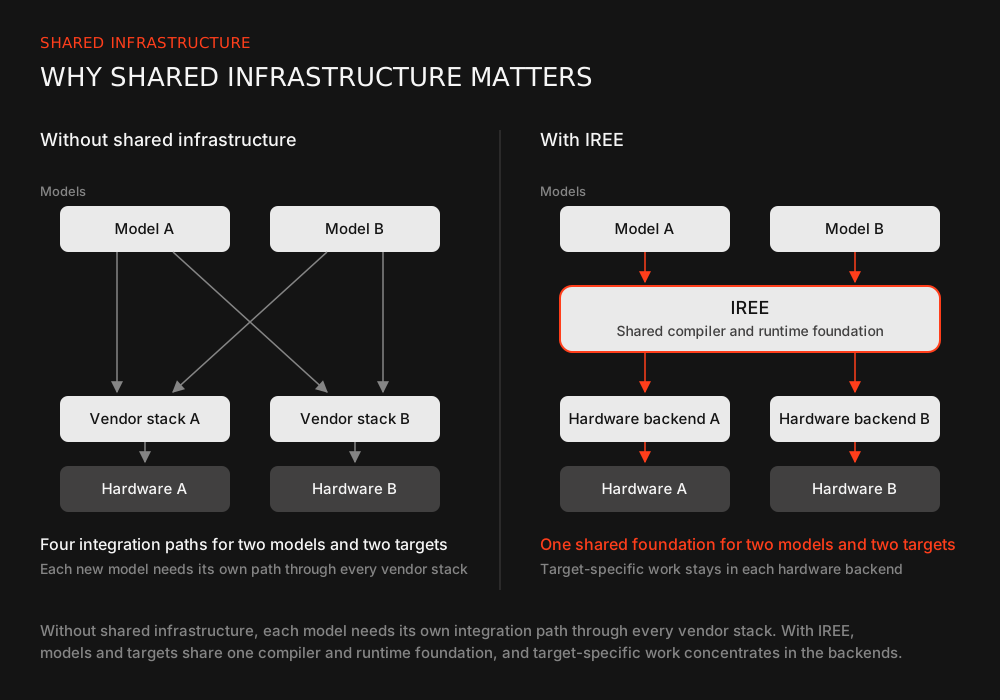
We want to strengthen IREE as shared infrastructure for deploying AI across CPUs, GPUs, NPUs, and heterogeneous systems.
“We’re increasing our engineering investment in IREE, not only by contributing code, but by taking on more responsibility for reviewing pull requests and maintaining areas of the project. A healthy open-source project needs engineers to help carry the ongoing maintenance work as well as contribute new features. We’re committing more Roofline engineering time to that ongoing effort, and we hope more contributors will join us in carrying it forward.”
— Maximilian Bartel, CTO at Roofline and Chair of the IREE Technical Steering Committee
Broader participation is an important part of strengthening IREE. We want more semiconductor and IP companies, research organizations, engineers, and researchers involved in the project, bringing new hardware requirements and technical expertise into the community.
A wider contributor and maintainer base helps IREE reflect more real hardware requirements, spreads the work of solving common deployment problems across the ecosystem, and keeps the project useful across different processors, products, and commercial interests as AI deployment requirements evolve.
Roofline contributes to IREE alongside other organizations and individual developers. Maximilian’s role as TSC Chair operates within the project’s existing governance structure, with technical decisions made through the TSC’s established processes.
IREE remains an open-source, sandbox-stage project within the LF AI & Data Foundation. The IREE Technical Steering Committee oversees the project’s technical direction under the IREE Technical Charter, and TSC meetings are open to everyone.
Our CTO, Maximilian Bartel, is serving as Chair of the TSC. The Chair presides over TSC meetings and helps coordinate the committee’s work, but technical oversight remains with the TSC rather than with Roofline or the Chair individually. The TSC elects its Chair from within the project’s governance structure.
Developers can participate through IREE’s GitHub repositories, issues, technical discussions, and community channels. Engineers and organizations can contribute code or documentation, join technical discussions, and help maintain areas of the project.
Our open-source work and our commercial deployment work use the same underlying compiler and runtime foundations.
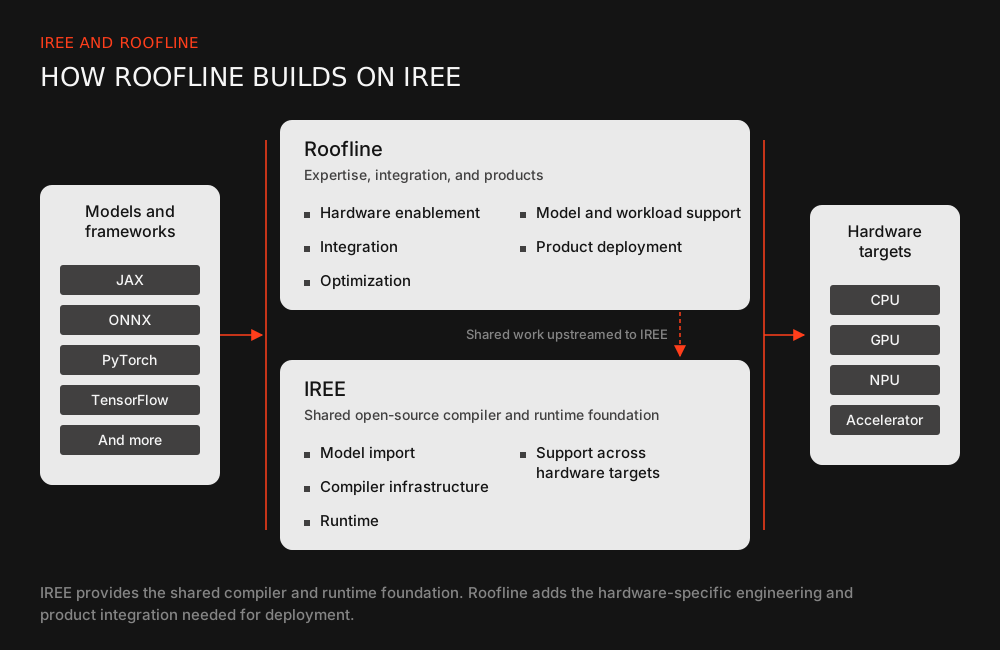
When we solve a deployment problem that belongs in shared infrastructure, the underlying capability can strengthen the common foundation rather than remaining isolated within one hardware integration. When other IREE contributors improve shared compiler and runtime infrastructure, we can build on those improvements too.
The practical benefit is less repeated generic engineering as models and hardware evolve.
IREE provides the shared compiler and runtime foundation for deploying AI across different hardware targets. Roofline turns that foundation into product-ready deployment infrastructure through hardware enablement, integration, and the validation and testing of the models and targets our customers need.
IREE already has an active contributor community, open technical governance, and a growing role in AI deployment infrastructure.
We want more engineers and organizations working on compilers, runtimes, AI hardware, and model deployment to participate in the project, so IREE can reflect a wider range of real deployment requirements and remain useful across different hardware and use cases.
There are several ways to get involved. You can contribute code or documentation through the IREE GitHub repository, open or respond to issues, join technical discussions, attend community and TSC meetings, or help maintain an area of the project. Organizations can also bring new hardware requirements, deployment challenges, and engineering experience into the community.
IREE will be stronger if the people building AI hardware and deployment software help shape the shared infrastructure they depend on. We want to make it easier for more engineers and organizations to contribute, collaborate, and help IREE evolve with the models, hardware, and deployment requirements still to come.
If you have questions, ideas, or want to get involved, join the conversation through IREE GitHub Discussions or the IREE Discord. You can also take part in community meetings to discuss technical work, project priorities, and areas where contributors can help.
Today, Liquid AI released their new 230M parameter LLM. In their words, it's "the smallest model yet, built to run anywhere (CPUs, NPUs, and GPUs) to enable agentic applications on phones, robots, home and network automation devices.
"We are excited to showcase day-0 support with roofline's deployment tools.
Agentic home automation sounded exciting, so the demo below features a smart washing machine running a full multimodal workflow: LFM2.5-VL-450M provides visual intelligence, while LFM2.5-230M serves as the orchestration agent controlling the machine.
Both models are fully compiled and run on the CPU and eIQ® Neutron NPU on NXP Semiconductors' i.MX 95, demonstrating how new foundation models can instantly move from release to real-world edge deployments.Congrats to the Liquid AI team on the release!
#EdgeAI#AIDeployment#AICompiler#MLIR#IREE#Roofline#CoFundedByTheEU
MoE powers many of today's strongest LLMs. By activating only the experts each token actually needs, it packs far more performance into the same compute budget, a limited resource on the edge. But this only pays off if your deployment stack can handle the dynamic expert routing MoE depends on, and until now, edge AI compilers couldn't.
roofline closes this gap by bringing native MoE support to its IREE-based deployment stack.
In our latest case study, we compile and run MoE models end-to-end, from IBM's Granite 3.1 1B-A400M, through Liquid AI's LFM2-8B-A1B, up to Qwen-REAP-15B-A3B. The case study walks through the operators that were missing, how we enabled them, and includes a demo of the compiled models running end-to-end: https://lnkd.in/eqqtneKV
#EdgeAI#AIDeployment#AICompiler#MLIR#MoE#Roofline#CoFundedByTheEU
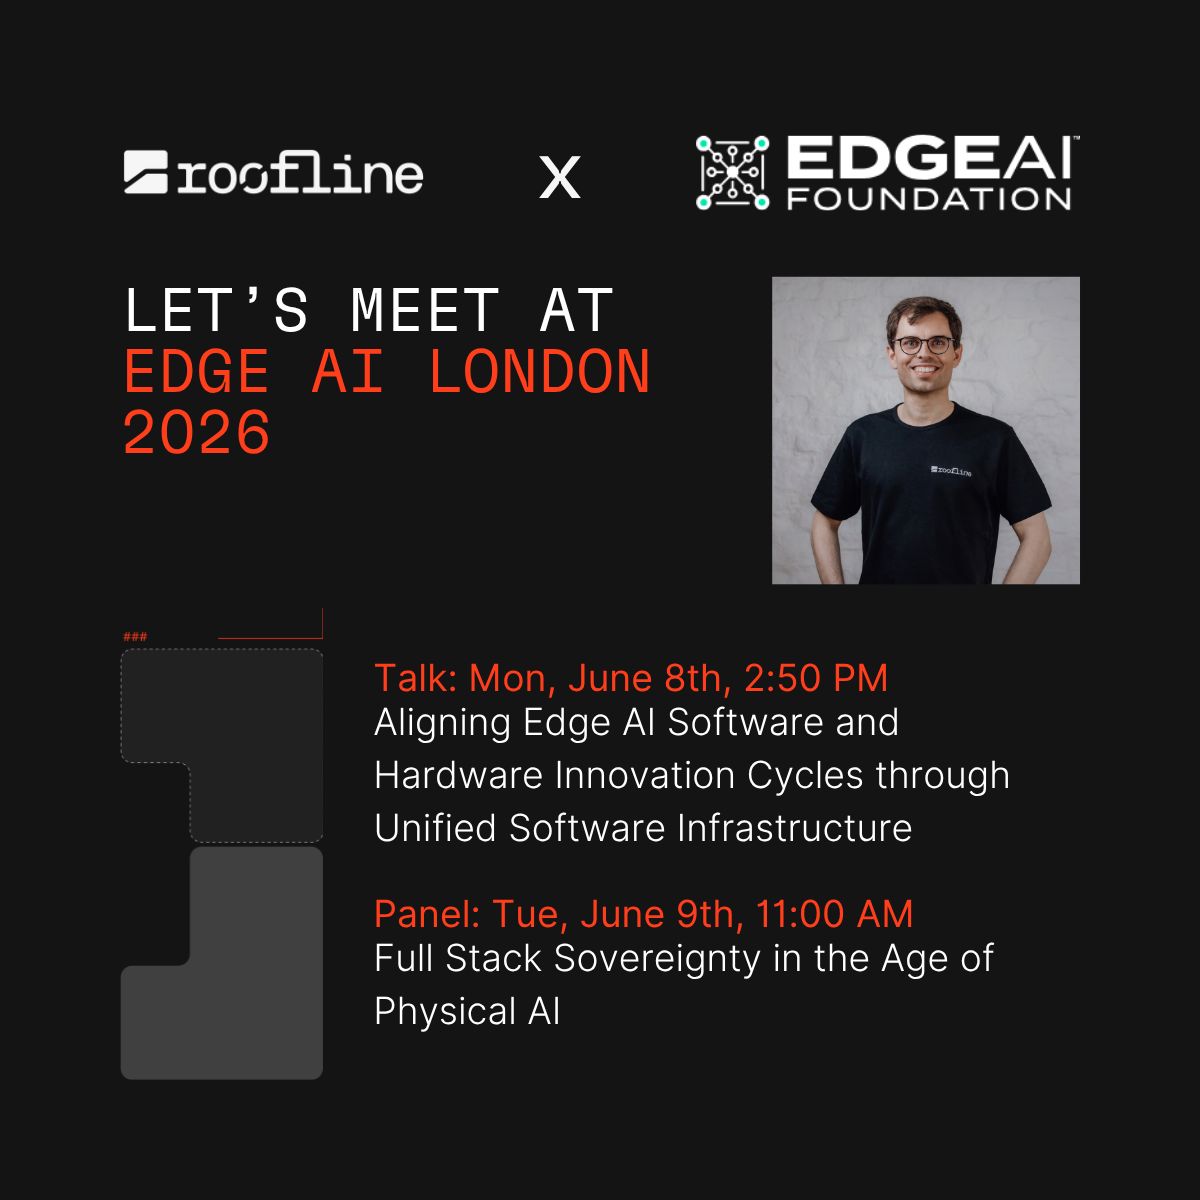
Our founders Jan Moritz Joseph and Dr. Thomas Zimmermann are excited to join EDGE AI FOUNDATION's Edge AI London 2026 on June 8 and 9, showcasing and discussing our latest progress.
🎤 Talk: In the talk 𝘈𝘭𝘪𝘨𝘯𝘪𝘯𝘨 𝘌𝘥𝘨𝘦 𝘈𝘐 𝘚𝘰𝘧𝘵𝘸𝘢𝘳𝘦 𝘢𝘯𝘥 𝘏𝘢𝘳𝘥𝘸𝘢𝘳𝘦 𝘐𝘯𝘯𝘰𝘷𝘢𝘵𝘪𝘰𝘯 𝘊𝘺𝘤𝘭𝘦𝘴 𝘵𝘩𝘳𝘰𝘶𝘨𝘩 𝘜𝘯𝘪𝘧𝘪𝘦𝘥 𝘚𝘰𝘧𝘵𝘸𝘢𝘳𝘦 𝘐𝘯𝘧𝘳𝘢𝘴𝘵𝘳𝘶𝘤𝘵𝘶𝘳𝘦, Jan Moritz Joseph will show how a unified open-source compiler and runtime ecosystem can close the gap between model and hardware innovation cycles, with real customer use cases on production SoCs. ⏱️ Mon, June 8th, 2:50 PM GMT+1 @ Mainstage
🗣️ Panel: Jan Moritz Joseph will also join the panel 𝘍𝘶𝘭𝘭 𝘚𝘵𝘢𝘤𝘬 𝘚𝘰𝘷𝘦𝘳𝘦𝘪𝘨𝘯𝘵𝘺 𝘪𝘯 𝘵𝘩𝘦 𝘈𝘨𝘦 𝘰𝘧 𝘗𝘩𝘺𝘴𝘪𝘤𝘢𝘭 𝘈𝘐 alongside NXP Semiconductors, Infineon Technologies, STMicroelectronics and Innatera to discuss what full stack sovereignty means for Europe's AI industry. ⏱️ Tue, June 9th, 11:00 AM GMT+1 @ Mainstage
📷 Demo: We are also bringing our latest demos, including Liquid AI's LFM2.5-350M running on NXP Semiconductors eIQ Neutron NPU and Toradex's Verdin iMX95, showing what it looks like to bring edge AI into production.
Come by our booth and say hi. We are around for the full conference!
#EdgeAI#AICompiler#MLIR#IREE#Roofline
Modern CPUs accelerate AI inference using SIMD (Single Instruction, Multiple Data) instructions. Arm’s Scalable Vector Extension (SVE) is a modern SIMD extension that introduces a vector-length-agnostic programming model, removing the assumption of a fixed vector length at compile time. However, this flexibility introduces substantial compiler challenges in vectorization, tiling, and data layout strategies.
Expanding on the earlier joint Arm x roofline case study on SVE support, this paper lays the groundwork for data layout strategies for scalable vector ISAs and evaluates these on ARM SVE.
1. We enabled data-tiled Arm SVE support in MLIR/IREE by making data layouts and tile sizes parametric in the hardware vector length, rather than fixed at compile time. This means a single compiled AI model runs efficiently across Arm CPUs with different vector lengths.
2. Our SVE code generation matches and often outperforms IREE's existing NEON code generation (up to 1.5× speedup), confirming that scalable data layouts do not regress performance despite the added compiler complexity. It also outperforms PyTorch ecosystem frameworks, with speedups of up to 1.7× over ExecuTorch and 6× over TorchInductor
3. In a cycle-level simulator study, our generated code scales with increasing SVE vector length, reaching up to 3.4× speedup when moving from 128-bit to 512-bit SVE on compute-bound workloads.
Great work by Ege Beysel, Maximilian Bartel, and Jan Moritz Joseph, and thanks to Andrzej Warzyński for the continuously great collaboration.
Read the full paper: https://lnkd.in/dTwt__ar
#MLIR #LLVM #AICompiler #EdgeAI #AIDeployment #Roofline